4. Processes with Markovian Increments#
Authors: Lars Peter Hansen (University of Chicago) and Thomas J. Sargent (NYU)
\(\newcommand{\eqdef}{\stackrel{\text{def}}{=}}\)
4.1. Introduction#
Chapter 3 described some implications of processes with stationary increments. In this chapter, we add structure by modeling the increments as a stationary Markov process. Such processes are commonly used to model logs of key macroeconomic time series—GDP, capital and labor stocks, and price levels—that display stochastic growth additive over time. Chapter 8 explores the implications of exponentiating a process with stationary increments. Doing that transforms an arithmetically growing process to one that displays geometric stochastic growth.
4.2. Definition of additive functional#
Let \(\{W_{t+1} : t \ge 0\}\) be a \(k\)-dimensional stochastic process of unanticipated economic shocks. Let \(\{ X_t : t \ge 0 \}\) be a discrete-time stationary Markov process that is generated by initial distribution \(Q\) for \(X_0\) and transition equation
where \(\phi\) is a Borel measurable function. Let \(\left\{ \mathfrak{A}_t : t=0,1,... \right\}\) be the filtration generated by histories of \(W\) and \(X\); \(\mathfrak{A}_t\) serves as the information set (sigma algebra) generated by \(X_0, W_1, \ldots , W_t\). We presume that the conditional probability distribution for \(W_{t+1}\) conditioned on \(\mathfrak{A}_t\) depends only on \(X_t\). To assure that the process \(\{W_{t+1} : t \ge 0 \}\) represents unanticipated shocks, we restrict it to satisfy
We produce results that condition on a statistical model in the sense of Section Limiting Empirical Measures in Chapter 1, or equivalently on the invariant events. Given this, for notational simplicity, we simply assume that the stationary process \(\{X_t : t \ge 0\}\) is ergodic.[1] The Markov structure of \(\{ X_t \}\) makes the distribution of \((X_{t+1}, W_{t+1}) \) conditioned on \(\mathfrak{A}_t\) depend only on \(X_t\).[2]
Definition 4.1
A process \(\{ Y_{t} \}\) is said to be an additive functional if it can be represented as
for a (Borel measurable) function \(\kappa: {\mathbb R}^n \times {\mathbb R}^k \rightarrow {\mathbb R}\), or equivalently
where we initialize \(Y_0\) at some arbitrary random variable depending on date zero information, although formally speaking such a restriction is not needed for what follows.
For a given additive functional, we study the joint process:
with particular interest in the behavior of the \(\{ Y_t : t\ge 0 \}\) process. It is easy to see that a linear combination of two additive functionals \(\{Y_{t}^{[1]}\}\) and \(\{Y_{t}^{[2]}\}\) is itself an additive functional. If \(\kappa_1\) is used to construct the first process and \(\kappa_2\) the second process, then \(\kappa = \kappa_1 + \kappa_2\) can be used to construct the sum of the two processes.
A particular class of additive functionals will play a central role in what follows.
Definition 4.2
An additive functional \(\{ Y_t : t=0,1,...\}\) is said to be an additive martingale if \(E\left[ \kappa(X_{t}, W_{t+1}) \vert X_t \right] = 0.\)
Note that \(E\left[ \kappa( X_t, W_{t+1} ) \vert X_t \right] = 0\) implies the martingale restriction that we used previously:
Example 4.1
Suppose that
where \(\{ W_{t+1} : t\ge 0 \}\) is an i.i.d. sequence of standardized multivariate normally distributed random vectors, \({\mathbb A}\) is a stable matrix, and \({\mathbb B}\) has full column rank, and the random vector \(X_0\) is generated by initial distribution \(Q\) associated with the stationary distribution for the \(\{ X_t \}\) process. Here \(\mu(X_t)\) is the conditional mean of \(Y_{t+1} - Y_t\) and \(|\sigma(X_t)|^2\) is its conditional variance. When \(\sigma\) depends on \(X_t\), this is called a stochastic volatility model because \(|\sigma(X_t)|^2\) is a stochastic process. Conditional variances evolve stochastically over time.
In Example 4.1, when the conditional mean \(\mu(X_t) = 0\), the process \(\{Y_t \}\) is a martingale.
4.3. Extracting Martingales#
We can decompose an additive functional into a sum of components, one of which is an additive martingale that encapsulates all long-run stochastic variation as in Proposition 3.1. In this section, we show how to extract the martingale component. We adopt a construction like that used to establish Proposition 3.1 and proceed in four steps.
4.3.1. Martingale construction#
Construct the trend coefficient as the unconditional expectation:
Form the random variable \(H_t\) by computing multiperiod forecasts for each horizon and summing these forecasts over all horizons. Start by constructing
\[\overline \kappa(x) = E \left[ \kappa(X_t, W_{t+1}) - \eta \mid X_t = x \right].\]Thus
\[E \left[ \kappa(X_{t+j-1}, W_{t+j}) - \eta \vert X_t = x \right] = \mathbb T^{j-1} \overline \kappa (x)\]for \(j \ge 1.\) Summing the terms, construct
(4.3)#\[\begin{align} H_{t} = & \sum_{j=0}^\infty E\left[ \kappa(X_{t-1+ j}, W_{t+j}) - \eta \mid X_{t-1}, W_t \right] \cr = & \kappa(X_{t-1}, W_{t}) - \eta + \sum_{j=1}^\infty E\left[ \kappa(X_{t-1+ j}, W_{t+j}) - \eta \mid X_{t-1}, W_t \right] \cr = & \kappa(X_{t-1}, W_{t}) - \eta + \sum_{j=0}^\infty E \left[ \overline \kappa( X_{t+j} ) \mid W_t, X_{t-1} \right] \cr = & \kappa(X_{t-1}, W_{t}) - \eta + \sum_{j=0}^\infty {\mathbb T}^j \overline{\kappa} (X_t) \cr = & \kappa(X_{t-1}, W_{t}) - \eta + \left( \mathbb I - \mathbb T \right)^{-1} \overline \kappa(X_{t}) \cr \eqdef & \kappa_h(X_{t-1}, W_t) \cr \end{align}\]where \({\mathbb T}\) is the conditional expectation operator (2.1) of Chapter 2. The right side of the next to the last equation becomes a function of only \((X_{t-1},W_t)\) once we substitute \(\phi(X_{t-1},W_t)\) for \(X_t\) as implied by (4.1).
This construction requires that the infinite sum
\[\sum_{j=0}^\infty {\mathbb T}^j {\overline \kappa}(x) = \left( \mathbb I - \mathbb T \right)^{-1} \overline \kappa(x)\]converges in mean square under the stationary distribution for \(\{X_t: t\ge 0\}\). A sufficient condition for this is that \({\mathbb T}^m\) is a strong contraction in the sense of Definition 2.6 of Chapter 2 for some integer \(m \geq 1\) and \(\overline{\kappa} \in {\mathcal N}\), the mean-zero subspace (2.7) of Chapter 2.
Compute
\[\begin{split} H_t^+ & = E\left( H_{t+1} \mid {\mathfrak A}_t \right) \cr &= E \left[ \kappa_h(X_t, W_{t+1}) \mid X_t \right] \cr & \eqdef \kappa_+(X_t) \end{split}\]Substituting for \(\kappa_h\) and using \({\mathbb T}\) gives[3]
\[\begin{split}\begin{split} \kappa_+(x) & = E\left[\kappa(X_{t}, W_{t+1}) \mid X_{t} = x \right] - \eta + E\left[ \left(\mathbb I - \mathbb T \right)^{-1} \overline \kappa(X_{t+1}) \mid X_t = x \right] \\ & = E\left[\kappa(X_{t}, W_{t+1}) \mid X_{t}= x \right] - \eta + {\mathbb T} \left( \mathbb I - \mathbb T \right)^{-1} \overline \kappa(x). \end{split}\end{split}\]Build the martingale increment:
where
Observe that \(\kappa_m\) is the sum of two contributions
given by the terms on separate lines on the right side of this expression. The first is a contemporary contribution and the second is a long term contribution. By construction, the expectation of \(\kappa_m(X_t, W_{t+1})\) conditioned on \(X_t\) is zero.
Armed with these calculations, we now report a Markov counterpart to Proposition 3.1.
Proposition 4.1
Suppose that \(\{Y_{t} : t\ge 0\}\) is an additive functional, that \({\mathbb T}^m\) is a strong contraction on \({\mathcal N}\) for some \(m\), and that \(E[\kappa(X_{t},W_{t+1})^2] < \infty\). Then
Of the four terms in Proposition 4.1, the first is a linear time trend, the second an additive martingale, the third a stationary process with mean zero, and the fourth a time-invariant constant. The martingale component is itself an additive functional. If we happen to impose the initialization: \(Y_0 = - \kappa_+(X_0)\), then the fourth term is zero. We use the Proposition 4.1 decomposition as a way to associate a “permanent shock” with an additive functional. The permanent shock is the increment to the martingale.
4.4. Applications#
We now compute martingale increments for two models of economic time series.
4.4.1. Vector autoregression#
We apply the four-step construction in Algorithm Martingale construction when the Markov state \(\{ X_t \}\) follows a first-order VAR
where \({\mathbb A}\) is a stable matrix and \(\{ W_{t+1} : t\ge 0 \}\) is a sequence of independent and identically normally distributed random variables with mean vector zero and identity covariance matrix. The one-step ahead conditional covariance matrix of the time \(t+1\) shocks \(\mathbb{B} W_{t+1}\) to \(X_{t+1}\) equals \(\mathbb{B} \mathbb{B}'\). Let
where \({\mathbb D}\) and \({\mathbb F}\) are row vectors with the same dimensions as \(X_t\) and \(W_{t+1}\), respectively. For this example, the four steps of Algorithm Martingale construction become:
The trend growth rate is \(\eta\) as specified.
- \[\begin{split} {\overline \kappa}(X_t) & = {\mathbb D}X_t \cr \kappa_h(X_{t-1}, W_t) & = {\mathbb D} X_{t-1} + {\mathbb F} W_{t} + {\mathbb D}({\mathbb I} - {\mathbb A} )^{-1} X_t \end{split}\]
- \[\begin{split} \kappa_+(X_t) & = {\mathbb D} X_t + {\mathbb D} ({\mathbb I} - {\mathbb A} )^{-1}{\mathbb A} X_t \cr & = {\mathbb D}({\mathbb I} - {\mathbb A} )^{-1} X_t \end{split}\]
- (4.6)#\[\begin{split} \kappa_m(X_{t-1}, W_t) & = {\mathbb F} W_{t} + {\mathbb D} ({\mathbb I} - {\mathbb A} )^{-1} (X_t - {\mathbb A} X_{t-1} ) \cr & = \left[{\mathbb F} + {\mathbb D} ({\mathbb I} - {\mathbb A} )^{-1} {\mathbb B} \right] W_t. \end{split}\]
From Example 1.8, we expect the coefficient of the martingale increment to be the sum of impulse responses for the increment process \(\{ {\mathbb D} X_t + {\mathbb F} W_{t+1} : t\ge 0\}\). The impulse response function is the sequence of vectors:
Summing these vectors gives
as anticipated.
4.4.2. An economic rationale#
Recursive utility represents preferences using recursively-constructed continuation values. As an illustration, let \(V_t\) be the date \(t\) continuation value used to rank current and future consumption, and let \({\widehat V}_t\) denote its logarithm. Suppose that for the logarithm of consumption, \({\widehat C}_t = \log C_t\),
and
where the first two equations are backward looking and the third and fourth ones are forward looking. In particular, current \({\widehat V}_t\) depends on the future \({\widehat V}_{t+1}\) through the construction of \({\widehat R}_t.\) In turn, \({\widehat R}\) is a risk-adjusted certainty equivalent of the next period continuation value \({\widehat V}_{t+1}\). In particular, these preferences use an exponential risk adjustment as reflected in the formula for \({\widehat R}_t\) instead of the conditional expectation of the future continuation value. We restrict the subjective discount factor, \(\beta,\) to satisfy \(0 < \beta < 1,\) and the risk aversion parameter, \(\gamma,\) to satisfy \(\gamma \ge 1.\) The \({\mathbb A}\) matrix governing the state dynamics is stable. The forward equations typically require a terminal condition for the continuation value to be used in computing a solution for today’s continuation value iteratively. Here we impose time invariance by considering an infinite-horizon specification, one that could be constructed by taking a limit of finite horizon problems with zero terminal conditions.
These preferences are a special case of preferences of [Kreps and Porteus, 1978] and [Epstein and Zin, 1989] that feature a role for the intertemporal composition of risk. In the limiting case as \(\gamma \downarrow 1,\) \({\widehat R}_t\) is the conditional expectation allowing us to write the continuation value recursion as:
which can be solved forward to obtain:
Recalling that \({\widehat C}_t = \log C_t\), this limiting case gives discounted expected logarithmic utility as a way to assess alternative consumption processes.
When the process \(\{ {\mathbb D} X_t\}\) is highly persistent, there is said to be substantial “long-run risk” in consumption. [Bansal and Yaron, 2004] consider a process governing stochastic volatility that we abstract from in the computations that follow. While the illustrative calculations in what follows use the VAR-type application of [Hansen et al., 2008], some of the basic insights extend much more generally.
4.4.2.1. Computing continuation values#
To provide a Markov characterization of the continuation value process, it is convenient to subtract \({\widehat C}_t\) from both sides of the continuation-value equation:
and rewrite the risk adjustment as:
We have now constructed a transformed utility recursion expressed in terms of the logarithmic growth rate \({\widehat C}_{t+1} - {\widehat C}_t\) and the future counterparts. When \(\gamma = 1\), only conditional expectations of future logarithmic growth rates matter. Once we let \(\gamma > 1,\) the intertemporal composition of logarithmic growth rate risk comes into play.
Given the assumed dynamics for the growth rate in consumption, \({\widehat C},\) and the chosen representation of preferences, \({\widehat V}\) and \({\widehat C}\) turn out to be cointegrated. We use guess and verify to seek a solution of the form:
The coefficient vector \(\upsilon\) satisfies:
with a solution:
Notice that the formula for the coefficient \(\upsilon\) does not depend on the choice of \(\gamma\).
The scalar \({\sf v}\) satisfies:
where we have computed expectations using known calculations for log-normally distributed random variables. Solving this forward gives:
Observe that the first term in the square brackets of (4.9) is the average growth rate expressed in logarithms. The second term is negative and becomes more so as \(\gamma\) gets larger. As expected, it is zero when \(\gamma = 1.\) For this second contribution, it is revealing to inspect the \(\beta = 1\) limit. Observe that the limiting version of \(\upsilon\) is:
implying that the term of interest is
This term gives a variance adjustment to the continuation value equal to the product of \((1-\gamma)/2\) and the variance of the increment to the martingale component of the logarithm of consumption as reported in (4.6). When \(\gamma = 1,\) this variance adjustment is zero. Larger values of \(\gamma > 1\) increase the magnitude of this adjustment to the continuation value. The \(\beta = 1\) limit is pertinent because this parameter is often set close to unity in the macro-finance literature.
4.4.2.2. Shadow values#
So far we showed only how to construct the continuation-value process. Continuation values provide a way to rank alternative stochastic consumption choices. Intertemporal marginal valuations are also of interest, as they reveal shadow prices that can often be used to represent asset prices when expressed using the stochastic equilibrium consumption process. They also point to directions of improvement from suboptimal consumption processes. We provide a formula for marginal valuations by first computing an intertemporal counterpart to an indifference curve. Suppose we alter the date \(t+1\) consumption to be \({C}_{t+1} + \epsilon Z_{t+1} \) for a random variable, \(Z_{t+1}\), in the date \(t+1\) conditioning information set. To counteract this change, we alter the date \(t\) consumption to be \({C}_t - \pi_t(\epsilon)\) where \(\pi_t\) is the adjustment needed to leave the continuation value the same. Since the continuation value remains the same for all values of \(\epsilon\), the derivative with respect to \(\epsilon\) should be zero. Differentiating through the recursion gives:
We obtain the formula in the second line by applying the chain rule when we differentiate through the recursion. To elaborate, using the logarithmic utility recursion (4.8), we construct two marginal utilities familiar from logarithmic utility:
From the certainty-equivalent formula expressed in logarithms, we construct the marginal utility of the next-period logarithm of the continuation value:
Finally, the next-period marginal utility of consumption is
Putting these formulas together using the chain rule for differentiation gives a marginal utility contribution for the next-period consumption:
Now let \(v^+ = {\widehat V}_{t+1}\), \(c^+ = C_{t+1}\), \(C_t = c\), and \(r = {\widehat R}_t\) to obtain the computation reported in (4.11). Solving for \(\frac {d \pi_t}{d \epsilon}\vert_{\epsilon = 0}:\)
where
The random variable \(\frac {S_{t+1}}{S_t}\) is often referred to as the (one period) stochastic discount factor. It has three contributions, (i) a subjective discount factor, \(\beta\), (ii) a risk contribution, and (iii) an intertemporal substitution contribution. The risk contribution is in square brackets. It depends on the next-period continuation value and is forward looking. Importantly, this contribution introduces a long-term impact on short-term (one-period) valuation. Setting \(\gamma = 1\) makes the second contribution degenerate and gives the marginal valuation implied by discounted expected logarithmic utility. In effect formula (4.12) is the slope of an indifference curve indexed by the choice of the random variable \(Z_{t+1}.\) The random variable \(Z_{t+1}\) captures the exposure to uncertainty, and \(\frac {d \pi_t}{d \epsilon}\vert_{\epsilon = 0}\) is the implied shadow price of that exposure for a given consumption process.
4.4.2.3. Empirical example#
As an illustration, [Hansen et al., 2008] and [Hansen and Sargent, 2021] identify long-term risk in consumption by imposing cointegration on a VAR. By design, in what follows, we will abstract from model uncertainty and follow the common practice of plugging in estimates as if they were known with certainty. In Chapter 11, we investigate more generally the implications of a class of recursive utility preferences which nests this specification as a special case.
We construct a trivariate VAR system in which (1) the logarithm of proprietor’s income plus corporate profits, (2) the logarithm of personal dividend income, and (3) the logarithm of consumption have the same trend growth rate and martingale increment. Fig. 4.1 reports log differences in two time series.
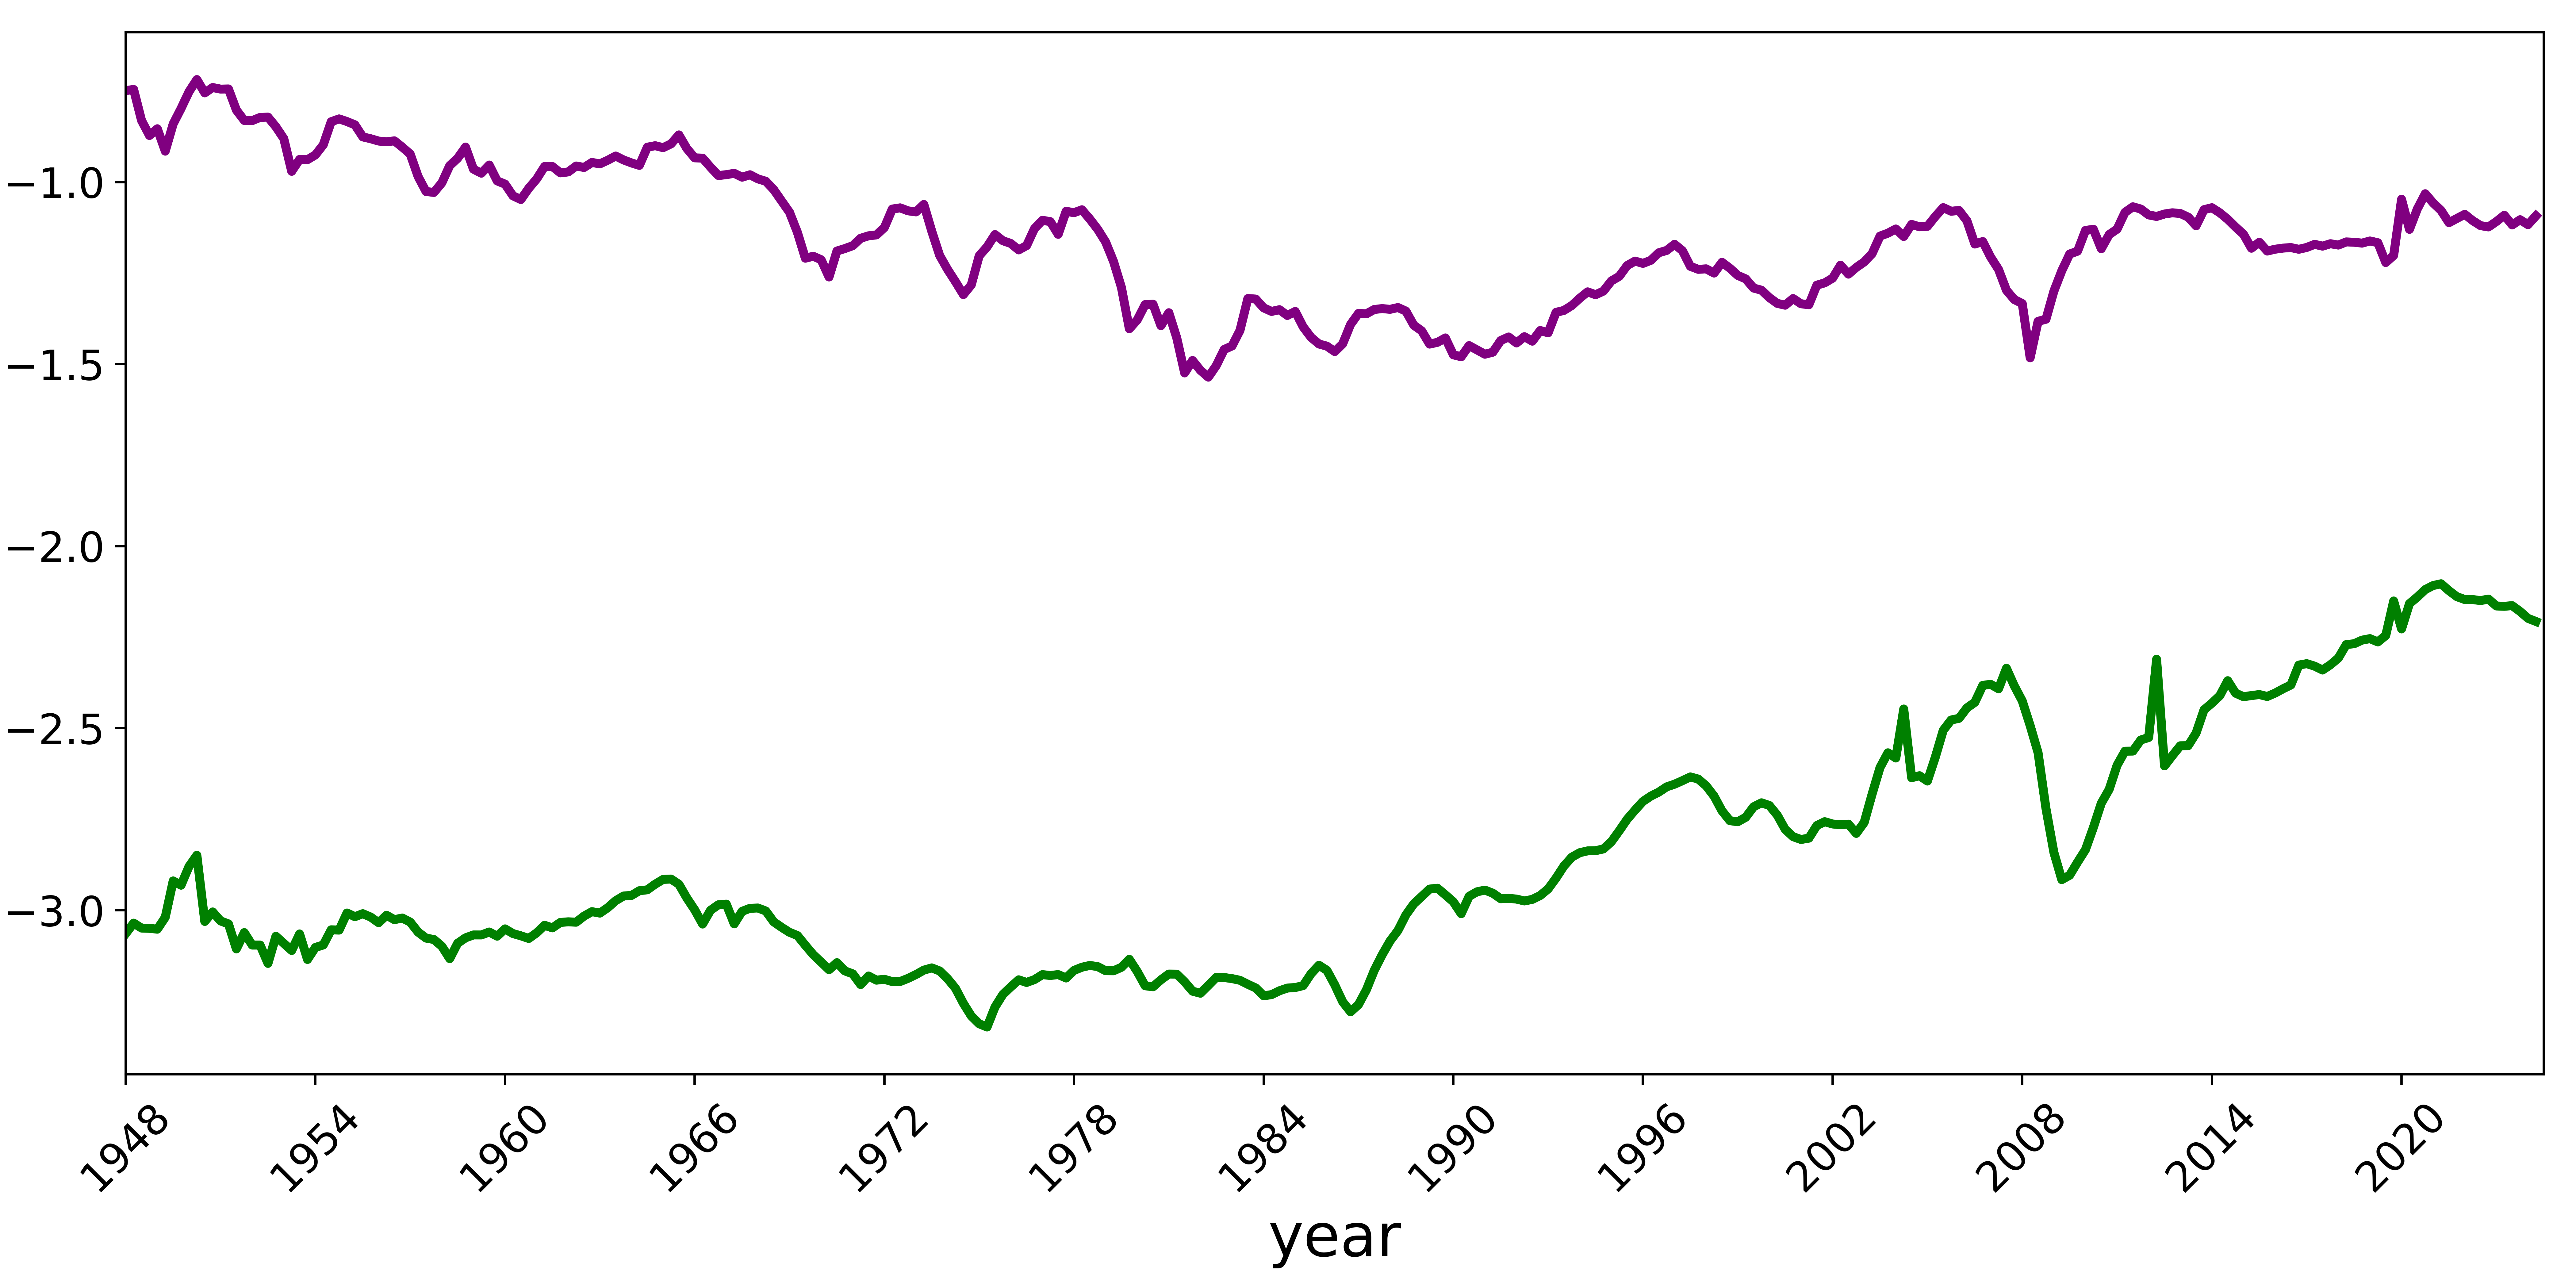
Fig. 4.1 Time series for the i) logarithm of proprietor’s income plus corporate profits relative to consumption (purple) and ii) the logarithm of personal dividend income relative to consumption (green).#
We follow [Hansen and Sargent, 2021] by constructing a VAR system in the steps that follow:
Form:
where \(C_t\) is consumption, \(Bus_t\) is business income, and \(Div_t\) is personal dividend income.
Construct
Express a vector autoregression and consumption growth as:
where \({\mathbb A}\) is a stable matrix (i.e., its eigenvalues are all bounded in modulus below unity) and \({\mathbb B}{\mathbb B}'\) is the innovation covariance matrix. Similar constructions can be done for the growth in business income and in dividend income by using the formulas:
Thus both can be constructed as linear transformations of \(Z_{t+1}\) and \(Z_t\).
Deduce a common permanent shock to all three time series using the approach described in Section Permanent shocks of Chapter 3 using formula
where
The initial scaling on the right side of the formula for the row vector, \({\mathbb F}^p,\) is done so that the permanent shock, \(W_{t+1}^p\), has standard deviation equal to one. We refer to shocks that are linear combinations of \(W_{t+1}\) formed with coefficient vectors orthogonal to \({\mathbb F}^p\) as transitory. Their long-term impulse response is zero. They are not uniquely defined without further (potentially economic) restrictions. This lack of uniqueness is evident because there are multiple three-dimensional vectors that are orthogonal to \({\mathbb F}^p.\) Linear combinations of any orthogonal vectors are also orthogonal to \({\mathbb F}^p.\) There is a two-dimensional subspace of such vectors.
We report the impulse responses of log consumption to the permanent shock and two transitory shocks in Fig. 4.2. All three shocks are normalized to have a unit standard deviation and the responses are multiplied by 100. The permanent shock has a substantial impact that builds over time. Its limiting value is \(|{\mathbb D} \left({\mathbb I} - {\mathbb A}\right)^{-1}{\mathbb B} + {\mathbb F} |\), which we verified contributes to the continuation value of consumption as reflected in (4.10) and to the implied marginal valuation as described in Section Shadow values.
The magnitude of the limiting version of this response is pertinent for the long-run risk model for the limiting case in which the subjective rate of discount is zero. Measurement of long-term impacts can be challenging as we will see in the next chapter.
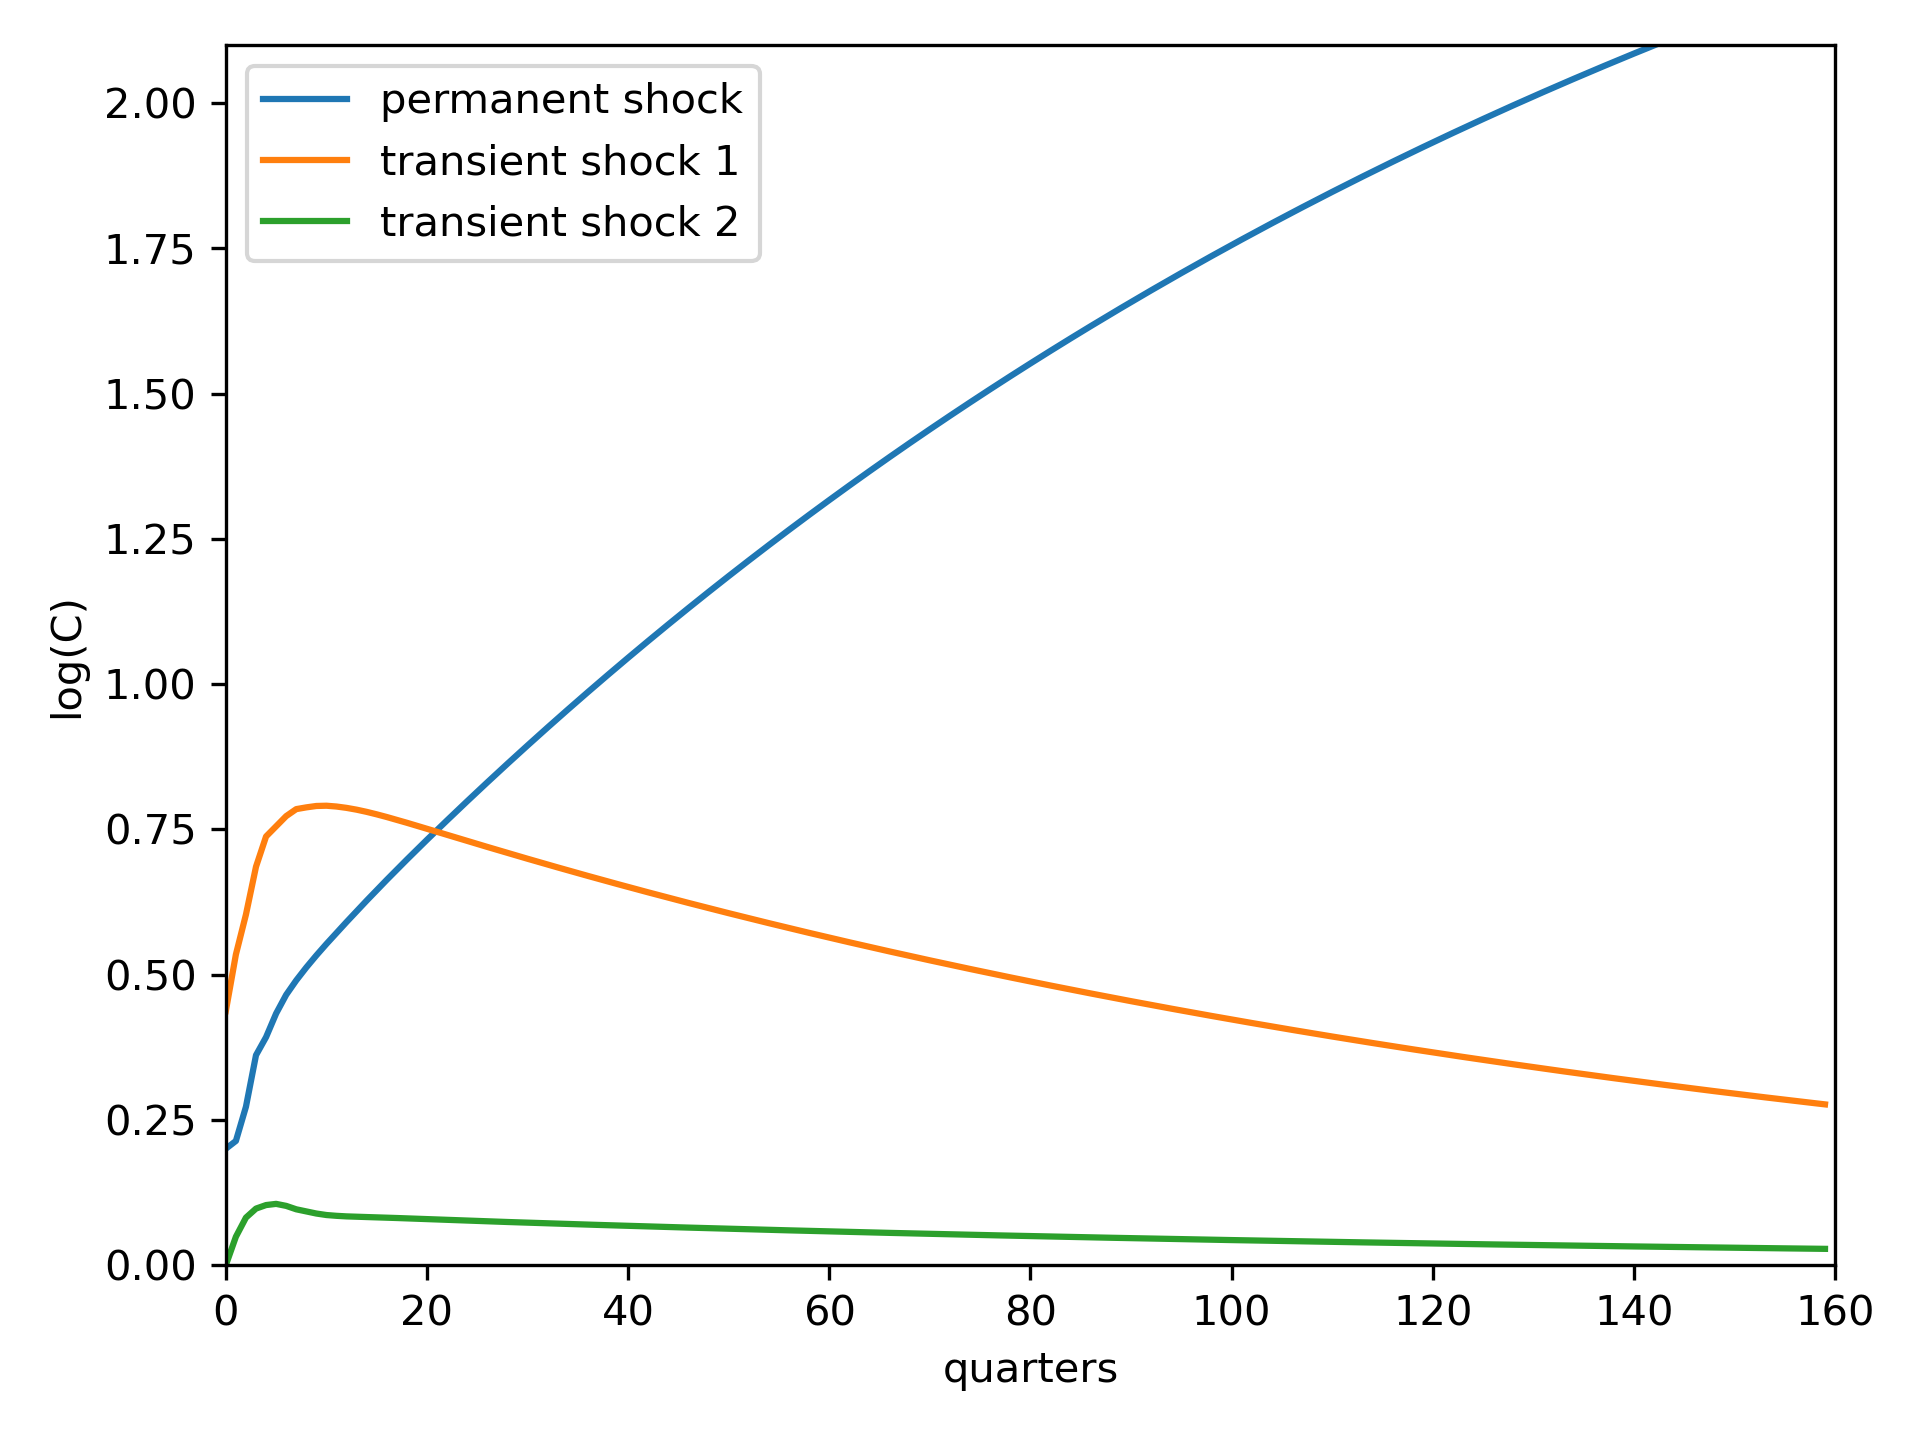
Fig. 4.2 Impulse responses of log consumption to permanent and two transitory shocks. The blue curve depicts the responses to a permanent shock. Responses to other transitory shocks are linear combinations of the two that are plotted.#
While vector autoregressions are very tractable and commonly used, they have two limitations. The shocks feed into the system in a linear way with constant coefficients. Thus there is no scope for stochastic volatility. The implied linear responses exclude the possibility of large discrete changes, sometimes conceived as regime shifts or as large abrupt contributions to the Markov process dynamics. We address these limitations in the next two subsections.
4.4.3. A quadratic approximation of state dynamics#
We follow [Lombardo and Uhlig, 2018] by considering the following family of stochastic processes indexed by a scalar perturbation parameter \(\mathsf{q}\):[4]
Here \(X\) is an \(n\)-dimensional stochastic process and \(\{W_{t+1}\}\) is an i.i.d. sequence of normally distributed random vectors with conditional mean vector \(0\) and conditional covariance matrix \(I\). We parameterize this family so that \({\sf q} = 1\) gives the process of interest.
We denote the zero-order expansion \({\sf q} = 0\) limit as:
and assume that there exists a second-order expansion of \(X_{t}\) around \(\mathsf{q} = 0\):
where \(X_t^1\) is a first-order contribution and \(X_t^2\) is a second-order contribution. The processes \(X^1\) and \(X^2\) are the first and second derivatives of \(X\) with respect to the perturbation parameter \({\sf q}\), evaluated at \({\sf q} = 0\). Processes \(X_t^j, j=0, 1, 2\) have a recursive structure: first compute the stochastic process \(X_{t}^0,\) then the process \(X_{t}^1\) (it depends on \(X_t^0\)), and finally the process \(X_{t}^2\) (it depends on both \(X_{t}^0\) and \(X_{t}^1\)).
In the discussion that follows, we use a prime \('\) to denote a transpose of a matrix or vector. When we include \(x'\) in a partial derivative of a scalar function it means that the partial derivative is a row vector. Consistent with this convention, let \(\psi^i_{x'}\), the \(i^{th}\) entry of \(\psi_{x'}\), denote the row vector of first derivatives with respect to the vector \(x\), and similarly for \(\psi^i_{w'}\). Since \({\sf q}\) is scalar, \(\psi_{\sf q}^i\) is the scalar derivative with respect to \({\sf q}\). Derivatives are evaluated at \(X_t^0\), which in many examples is invariant over time, unless otherwise stated. This invariance follows when we impose a steady state on the deterministic system.
The first-derivative process obeys a recursion
that we can write compactly as the following first-order vector autoregression:
We assume that the matrix \(\psi_{x'}\) is stable in the sense that all of its eigenvalues are strictly less than one in modulus.
For future reference, note that the mean (conditioned on the parameters of the first-order approximation) satisfies:
implying that:
It is natural for us to denote second derivative processes with double subscripts. For instance, for the double subscript used in conjunction with the second derivative matrix of \(\psi^i\), the first subscript without a prime (\('\)) reports the row location; the second subscript with a prime (\('\)) reports the column location. Differentiating recursion (4.17) gives:
Recursions (4.17) and (4.18) have a linear structure with some notable properties. The law of motion for \(X^0\) is deterministic and is time invariant if (4.14) comes from a stationary \(\{X_t\}\) process. Dynamics of \(X^2\) are nonlinear only in \(X^1\) and \(W_{t+1}\). Thus, stable dynamics for \(X^1\) that prevail when \(\psi_{x'}\) is a stable matrix imply stable dynamics for \(X^2\).
We compute the mean of \(X^2\) by solving:
where \(\Psi_{xx'}\) is the mean of
Thus
Let \(Y\) denote consumption or some other macro aggregate and let \({\widehat Y}\) be its logarithm. Suppose that \({\widehat Y}\) evolves as:
Approximate this process by:
where
The first-order contribution, the \(X^1\) process, is just a first-order autoregression, so we may construct the trend and martingale components as before. The trend coefficient for the \(Y^2\) process can be computed from the mean of \(X^1\), the mean of \(X^2\) and second-moment matrix of \(X^1\). Following the steps for a martingale construction, we may construct a recursion to compute the terms of interest. Indeed, we may apply our Markov algorithm from Proposition 4.1 for extracting the trend and martingale components of the process \(\{Y_t : t=0,1,... \}\). These constructions require algorithms, which turn out to be straightforward to implement.
As we will illustrate in Chapter 11, for models with endogenous investment and savings, consumption dynamics and some of the state dynamics emerge as equilibrium outcomes. We use the approximating processes (4.16) and (4.19) as inputs for constructing an approximate continuation value process and its risk-adjusted counterpart under recursive utility preferences.
4.4.4. Growth-Rate Regimes#
We construct a Proposition 4.1 decomposition for a model with persistent switches in the conditional mean and volatility of the growth rate \(Y_{t+1}- Y_t\).
Suppose that \(\{X_t : t \ge 0\}\) evolves according to an \(n\)-state Markov chain with transition matrix \({\mathbb P}\). Realized values of \(X_t\) are coordinate vectors in \({\mathbb R}^n\). Suppose that \({\mathbb P}\) has only one unit eigenvalue. Let \({\bf q}\) be the column vector of stationary probabilities associated with that unit eigenvalue, normalized so that \({\bf q} \cdot {\bf 1}_n = 1\) and
Consider an additive functional satisfying
where \(\{ W_{1,t} \}\) is an i.i.d. sequence of multivariate standard normally distributed random vectors. Following [Sclove, 1983], [Hamilton, 1989], [Sims and Zha, 2006], among others, the stationary Markov \(\{X_t : t \ge 0 \}\) process induces discrete changes in both the conditional mean and the conditional volatility of the growth rate process \(\{ Y_{t+1} - Y_t \}\).
Observe that \( E (X_{t+1} | X_t ) ={\mathbb P}' X_t \) and let
Thus we can represent the evolution of the Markov chain as
where \(\{W_{2,t+1} : t \ge 0 \}\) is an \(n \times 1\) discrete-valued vector process that satisfies \(E ( W_{2,t+1} | X_t) = 0 .\)
We again apply the four-step construction in Algorithm Martingale construction.[5]
- \[\eta = {\mathbb D} {\bf q} \]
- \[H_t = {\mathbb D} (X_{t-1} - {\bf q}) + {X_{t-1}}'{\mathbb F} W_{1,t} + {\mathbb D}\left({\mathbb I} - {\mathbb P}'\right)^{-1} (X_t - {\bf q}) \]
- \[H_t^+ = E\left( H_{t+1} \mid X_t \right) = {\mathbb D} \left( X_{t} - {\bf q} \right) + {\mathbb D}\left({\mathbb I} - {\mathbb P}'\right)^{-1} {\mathbb P}'(X_t - {\bf q})\]
which implies that
\[\kappa_+(x) = {\mathbb D} \left( x - {\bf q} \right) + {\mathbb D}\left({\mathbb I} - {\mathbb P}'\right)^{-1} {\mathbb P}' \left(x - {\bf q}\right)\] - \[G_t = H_t - H_{t-1}^+ = {X_{t-1}}'{\mathbb F} W_{1,t} + {\mathbb D}\left({\mathbb I} - {\mathbb P}'\right)^{-1} W_{2,t}\]
where we have substituted from equation (4.20).
The martingale increment has both continuous and discrete components:
4.5. Summary#
An additive functional is built from a Markov state by \(Y_{t+1} - Y_t = \kappa(X_t, W_{t+1})\). The four steps of Algorithm Martingale construction extract from it the components of Proposition 4.1, the Markov counterpart of Proposition 3.1. Unlike that earlier result, this one is constructive: it requires only the operator \({\mathbb T}\) of Chapter 2. For the vector autoregression of Section Vector autoregression the martingale increment is \(\left[{\mathbb F} + {\mathbb D}({\mathbb I}-{\mathbb A})^{-1}{\mathbb B}\right]W_t\), the sum of the impulse responses.
The recursive utility example of Section An economic rationale introduces objects that the rest of the book uses: a continuation value, a certainty equivalent that adjusts for risk, and the stochastic discount factor (4.12) obtained as the slope of an indifference curve. Chapter 11 develops those preferences and their robustness interpretation; Chapter 8 studies what happens when an additive functional is exponentiated.
4.6. Exercises#
Exercise 4.1 (A higher-order autoregression in companion form)
Everything in this chapter presumes a first-order Markov state. This exercise shows that the restriction costs nothing.
Suppose that \(\{ X_t : t=0,1,\ldots \}\) is an \(n\)-dimensional process satisfying
where \({\mathbb B}_1\) is square and \(W_{t+1}\) is normally distributed with mean zero and covariance matrix \({\mathbb I}_n\). Construct the stacked state
(a) Show that \(\{X_t^a\}\) is a first-order vector autoregression \(X_{t+1}^a = {\mathbb A} X_t^a + {\mathbb B} W_{t+1}\), exhibiting \({\mathbb A}\) and \({\mathbb B}\) explicitly.
(b) Suppose \({\mathbb A}\) is stable. Propose a stationary distribution for \(\{X_t^a\}\).
(c) The construction in (a) makes \({\mathbb B}{\mathbb B}^\top\) singular even though \({\mathbb B}_1{\mathbb B}_1^\top\) is not. Which claim in this chapter, or in Chapter 2, does that singularity bear on?
Exercise 4.2 (Martingale increment variance versus increment variance)
Suppose that
for a fixed vector \(\sigma \neq 0\), and let \(Y_{t+1} = Y_t + X_{t+1}\).
(a) Find the martingale component of the \(\{Y_t\}\) process and compute the variance of its increment.
(b) Compute the variance of \(X_t\).
(c) Form the ratio of the two variances. Show that it does not depend on \(\sigma\), and evaluate it.
(d) Which variance is larger when \(\beta > 0\)? When \(\beta < 0\)? Explain the economics: what is it about the pattern of the impulse responses in the two cases that makes the long-run variance larger or smaller than the one-period variance?
Exercise 4.3 (Two additive functionals that are cointegrated)
Consider a vector time series model
with \({\mathbb A}\) stable and
Write \({\sf u}_1\) and \({\sf u}_2\) for the first two coordinate vectors.
(a) Verify that \(\mu\) is the stationary mean of \(X_t\).
(b) Deduce formulas for \(\kappa_1\) and \(\kappa_2\) such that \(Y_{t+1}^1 - Y_t^1 = \kappa_1(X_t, W_{t+1})\) and \(Y_{t+1}^2 - Y_t^2 = \kappa_2(X_t, W_{t+1})\).
(c) Apply Algorithm Martingale construction to deduce the trend coefficients and martingale increments for \(Y^1\) and \(Y^2\). Show that both coincide, and that the common martingale coefficient is \({\sf u}_2^\top \left({\mathbb I} - {\mathbb A}\right)^{-1}{\mathbb B}\).
(d) Verify that \(Y^1\) and \(Y^2\) are cointegrated in the sense of Chapter 3 and give the cointegrating vector.
Exercise 4.4 (From the continuation value to the stochastic discount factor)
Section An economic rationale poses the recursive preference specification (4.8) for a first-order VAR and Section Shadow values shows how to pass from the continuation value to one-period marginal valuations. Carry the calculation through.
(a) Using the solution \({\widehat V}_t - {\widehat C}_t = \upsilon X_t + {\sf v}\), produce a formula for \(\log S_{t+1} - \log S_t\).
(b) Suppose that
for a row vector \(\zeta\). Use properties of the log-normal distribution to show that \(Z_{t+1}\) has conditional expectation equal to one, so that it is an admissible perturbation in (4.12).
(c) Produce a formula for the shadow price \(\frac{d \pi_t}{d \epsilon}\vert_{\epsilon = 0}\) of that exposure, and show that
for a row vector \(\xi\) that you should identify.
(d) Think of \(\zeta\) as a particular exposure to the uncertainty induced by \(W_{t+1}\). Discuss how the price of that exposure depends on \(\gamma\). What does \(\xi\) converge to as \(\beta \uparrow 1\), and how does that connect to (4.6) and (4.10)?
Exercise 4.5 (Continuation values under growth-rate regimes)
Section Growth-Rate Regimes analyzes an additive functional whose growth rate switches with an \(n\)-state Markov chain. Combine that specification with the recursive preferences (4.8) of Section An economic rationale.
Let \(X_t\) be a coordinate vector in \({\mathbb R}^n\) evolving with transition matrix \({\mathbb P}\), and let log consumption satisfy
with \(\{W_{1,t}\}\) an i.i.d. sequence of standard normal vectors independent of the chain. Write \({\mathbb D}_i\) for the \(i^{th}\) entry of \({\mathbb D}\) and \({\mathbb F}_i\) for the \(i^{th}\) row of \({\mathbb F}\), the ones selected when \(X_t\) is the \(i^{th}\) coordinate vector.
(a) Guess that \({\widehat V}_t - {\widehat C}_t = \upsilon \cdot X_t\) for an \(n\)-dimensional vector \(\upsilon\), so that the continuation value takes one of \(n\) values. Derive the system of equations that \(\upsilon\) must satisfy.
(b) Show that when \({\mathbb F}_i\) and \({\mathbb D}_i\) do not vary with \(i\), your system collapses to the constant \(\upsilon\) that (4.9) would deliver.
(c) Contrast this with the VAR case of Section Computing continuation values, where \(\upsilon\) solved a linear system. What makes the regime-switching system nonlinear, and which preference parameter would have to be set to remove the nonlinearity?
4.7. Answers#
Solution to Exercise 4.1 (A higher-order autoregression in companion form)
(a) Stack and pad:
The top block reproduces the original recursion and the bottom block is the identity \(X_t = X_t\), which makes the lagged value available as a component of the date \(t+1\) state.
(b) With \({\mathbb A}\) stable, the argument of Section Vector Autoregressions of Chapter 2 applies verbatim: the stationary distribution is \({\mathcal N}(0, \Sigma)\) where \(\Sigma\) is the unique positive semidefinite solution of the discrete Lyapunov equation \(\Sigma = {\mathbb A}\Sigma{\mathbb A}^\top + {\mathbb B}{\mathbb B}^\top\), equivalently \(\Sigma = \sum_{j=0}^\infty {\mathbb A}^j {\mathbb B}{\mathbb B}^\top \left({\mathbb A}^j\right)^\top\).
(c) It bears on the caveat attached to Example 2.1 in Chapter 2: when \({\mathbb B}{\mathbb B}^\top\) is singular the transition distribution has no density with respect to Lebesgue measure on the full state space, and the footnote there notes that this is typical precisely because first-order representations of higher-order autoregressions are built this way. The stationary distribution here is supported on the \(n\)-dimensional set traced out by \(\left(X_t, X_{t-1}\right)\) pairs rather than on all of \({\mathbb R}^{2n}\). Nothing in the martingale construction of this chapter requires a density, so the algorithm goes through; what fails is the literal reading of Definition 2.2.
Solution to Exercise 4.2 (Martingale increment variance versus increment variance)
(a) The moving-average coefficients are \(\alpha_j = \beta^j \sigma\). By Section Permanent shocks of Chapter 3, the martingale increment is \(\alpha(1)\cdot W_t\) with
so the variance of the martingale increment is \(|\alpha(1)|^2 = \frac{|\sigma|^2}{(1-\beta)^2}\).
(b) Since the \(W\)’s are orthonormal,
(c) The ratio is
which is free of \(\sigma\) because \(\sigma\) scales both variances identically.
(d) The ratio exceeds one when \(\beta > 0\) and is less than one when \(\beta < 0\). When \(\beta > 0\) a shock moves \(X\) in the same direction for many periods, so its effects on the level of \(Y\) cumulate and the long-run variance is amplified; in the limit \(\beta \uparrow 1\) the ratio diverges. When \(\beta < 0\) the responses alternate in sign and partially cancel when summed, so the permanent effect is smaller than the one-period variance; as \(\beta \downarrow -1\) the ratio goes to zero and the process approaches one with no permanent component at all.
Proposition 3.2 of Chapter 3 warns of this in general. The variance relevant for the central limit approximation is the variance of the martingale increment, not of the increment itself. The two can differ by an arbitrarily large factor in either direction.
Solution to Exercise 4.3 (Two additive functionals that are cointegrated)
(a) Taking unconditional expectations, \(\mu_X = {\mathbb A}\mu_X + \left({\mathbb I} - {\mathbb A}\right)\mu\), so \(\left({\mathbb I} - {\mathbb A}\right)\mu_X = \left({\mathbb I} - {\mathbb A}\right)\mu\). Stability of \({\mathbb A}\) makes \({\mathbb I} - {\mathbb A}\) nonsingular, so \(\mu_X = \mu\).
(b) The second component of \(X_{t+1}\) is \(Y_{t+1}^2 - Y_t^2\), so
For \(Y^1\), add and subtract \(Y^2\):
so that
(c) Write each in the form \(\kappa_j = \eta_j + {\mathbb D}_j\left(X_t - \mu\right) + {\mathbb F}_j W_{t+1}\) used in Section Vector autoregression. Taking expectations,
so the two trend coefficients agree. This had to happen: \(Y^1 - Y^2 = {\sf u}_1^\top X\) is a component of a stationary process, so it cannot drift.
Reading off the remaining coefficients, \({\mathbb D}_2 = {\sf u}_2^\top {\mathbb A}\), \({\mathbb F}_2 = {\sf u}_2^\top {\mathbb B}\), and \({\mathbb D}_1 = \left({\sf u}_1+{\sf u}_2\right)^\top{\mathbb A} - {\sf u}_1^\top\), \({\mathbb F}_1 = \left({\sf u}_1+{\sf u}_2\right)^\top{\mathbb B}\). Step 4 of Algorithm Martingale construction, in the form (4.6), gives the martingale coefficient \({\mathbb F}_j + {\mathbb D}_j\left({\mathbb I}-{\mathbb A}\right)^{-1}{\mathbb B}\). For \(Y^2\),
using \({\mathbb I} + {\mathbb A}\left({\mathbb I}-{\mathbb A}\right)^{-1} = \left({\mathbb I}-{\mathbb A}\right)^{-1}\). For \(Y^1\) the same manipulation gives
the same object. The extra \({\sf u}_1\) terms cancel exactly.
(d) Both the trend coefficients and the martingale increments of \(Y^1\) and \(Y^2\) coincide, so in the Proposition 4.1 decomposition the linear combination \(Y^1 - Y^2\) has zero trend and zero martingale component and is therefore stationary. The cointegrating vector is \((1, -1)\), determined as always only up to scale.
Solution to Exercise 4.4 (From the continuation value to the stochastic discount factor)
(a) From Section Shadow values,
whose logarithm is \(\log \beta + (1-\gamma)\left({\widehat V}_{t+1} - {\widehat R}_t\right) - \left({\widehat C}_{t+1} - {\widehat C}_t\right)\).
Substituting \({\widehat V}_{t+1} = {\widehat C}_{t+1} + \upsilon X_{t+1} + {\sf v}\) together with the dynamics (4.4)–(4.5), the only date \(t+1\) novelty is the shock, so
Log-normality then gives \({\widehat R}_t = {\mathbb E}\left({\widehat V}_{t+1}\mid{\mathfrak A}_t\right) + \frac{1-\gamma}{2}\left| {\mathbb F} + \upsilon {\mathbb B}\right|^2\), so
Therefore
(b) \(\zeta W_{t+1}\) is normal with mean zero and variance \(|\zeta|^2\), so \({\mathbb E}\left[\exp\left(\zeta W_{t+1}\right)\mid{\mathfrak A}_t\right] = \exp\left(\frac 1 2 |\zeta|^2\right)\) and the subtracted \(\frac 1 2 |\zeta|^2\) makes \({\mathbb E}\left(Z_{t+1}\mid {\mathfrak A}_t\right)=1\).
(c) Collect the coefficient on \(W_{t+1}\) in (a):
so that \(\frac{S_{t+1}}{S_t} = \exp\left(\xi W_{t+1} + c_t\right)\) with \(c_t\) known at date \(t\). Then
Since \({\mathbb E}\left(\frac{S_{t+1}}{S_t}\Big|{\mathfrak A}_t\right) = \exp\left(c_t + \frac 1 2 |\xi|^2\right)\), taking logarithms gives the stated decomposition. The shadow price of the exposure splits into a term that does not depend on the exposure, namely the price of a sure claim, and the inner product \(\xi\cdot\zeta\).
(d) The vector \(-\xi\) is the vector of one-period uncertainty prices. Writing
the first term is the familiar intertemporal-substitution contribution, present even under logarithmic utility. The second is the risk or robustness contribution and is proportional to \(\gamma - 1\). Raising \(\gamma\) therefore raises, linearly and without bound, the compensation demanded for exposure in the direction \({\mathbb F} + \upsilon{\mathbb B}\), while leaving directions orthogonal to it priced only through \(-{\mathbb F}\).
Recall \(\upsilon = \beta {\mathbb D}\left({\mathbb I}-\beta{\mathbb A}\right)^{-1}\). As \(\beta \uparrow 1\),
which is the coefficient on the martingale increment in (4.6); its squared norm appears in the continuation-value adjustment (4.10). So in the patient limit the priced direction is the permanent shock: what a one-period marginal valuation compensates is exposure to the component of the consumption process that never dies out. “Long-run risk” models exploit this mechanism. The price of a one-period claim is therefore sensitive to features of the dynamics that reveal themselves only over long horizons.
Solution to Exercise 4.5 (Continuation values under growth-rate regimes)
(a) Subtract \({\widehat C}_t\) from both sides of the recursion (4.8), as in Section Computing continuation values. With the unitary elasticity of intertemporal substitution implicit in the specification (4.8),
and
Condition on \(X_t\) being the \(i^{th}\) coordinate vector. The chain and the normal shock are independent, and \({\widehat C}_{t+1}-{\widehat C}_t = {\mathbb D}_i + {\mathbb F}_i W_{1,t+1}\) is normal, so the expectation factors:
Taking logarithms, dividing by \(1-\gamma\), and multiplying by \(\beta\),
This is a system of \(n\) equations in the \(n\) unknowns \(\upsilon_1,\ldots,\upsilon_n\), and it is solved conveniently by iterating from \(\upsilon = 0\).
(b) If \({\mathbb D}_i = \eta\) and \({\mathbb F}_i = {\mathbb F}\) for every \(i\), then a constant \(\upsilon_i = \upsilon\) is consistent: the log-sum-exp term becomes \(\frac{1}{1-\gamma}\log\left[\exp\left((1-\gamma)\upsilon\right)\sum_j {\sf p}_{ij}\right] = \upsilon\), since the rows of \({\mathbb P}\) sum to one. The system reduces to
whose solution \(\upsilon = \frac{\beta}{1-\beta}\left[\eta + \frac{1-\gamma}{2}|{\mathbb F}|^2\right]\) is (4.9) with the state-dependent terms switched off.
(c) In Section Computing continuation values the guess \({\widehat V}_t - {\widehat C}_t = \upsilon X_t + {\sf v}\) is affine in a state that enters the exponent linearly, so the risk adjustment produces only a constant and \(\upsilon\) solves the linear equation \(\upsilon = \beta \upsilon {\mathbb A} + \beta {\mathbb D}\). Here the state is a coordinate vector and the continuation value takes \(n\) separate values, so the risk adjustment acts through \(\frac{1}{1-\gamma}\log \sum_j {\sf p}_{ij}\exp\left[(1-\gamma)\upsilon_j\right]\), an exponential-tilting average of the \(\upsilon_j\)’s rather than a linear one. That is the source of the nonlinearity.
Setting \(\gamma = 1\) removes it. In the limit the log-sum-exp collapses to the ordinary conditional expectation \(\sum_j {\sf p}_{ij}\upsilon_j\), and the system becomes the linear \(\upsilon = \beta\left({\mathbb D} + {\mathbb P}\upsilon\right)\). With \(\gamma > 1\), the tilting overweights the regimes with low continuation values, which is the Murphy’s-law tilt that Section Shadow values prices.